Blog
Hands-on benchmarks and field notes from the Joshua8.AI lab: local inference, quantization, Blackwell GPUs, and building AI ventures.
- October 23, 2026 Can Claude Double the Speed of Qwen3.6-35B-A3B on an RTX 5090? Qwen3.6-35B-A3B NVFP4 on one 32 GB RTX 5090: single-request decode from 267 tok/s on vLLM to 626 on Elsa, an SGLang fork inspired by Penny Royal, with MTP,...
-
 October 22, 2026
Twice as Fast on the Same Card: Eight Weeks Later — Qwen3.8-Flash-Next on an RTX PRO 6000 Max-Q
Qwen3.8-Flash-Next on one 300 W RTX PRO 6000: decode from 94 to ~205 tok/s and a 3x larger KV pool via Penny Royal, plus a HiCache fix and...
-
 October 1, 2026
Doubling the Prompt Speed of LLMs on My $1,000 eBay Server
One llama.cpp setting, ubatch-size, nearly doubled prefill for eleven big MoE models on a $1,000 dual-Xeon, dual-Pascal eBay box. No new hardware.
-
 September 24, 2026
Two AIs, One Subdivision, Ninety Minutes
Grok and Claude each laid out a 20-lot Civil 3D subdivision from a one-line prompt in 45 minutes. One solved it; one only looked finished.
-
 September 10, 2026
The DMV Is Not a Suburb of the Bay
Oluwadi filed Joshua8.AI in a DMV regional edition, not a national list. Why region-first suits defense, integrators, and construction, and where it fails.
-
 September 9, 2026
The Apollonian Machine: What Nietzsche Would Say About the DRAM Crisis
The transformer is a beautiful diagram running on capacitors that leak. Nietzsche explains why we talk about the diagram, and why bandwidth beats FLOPs.
-
 September 7, 2026
A 127 GB Model on a 96 GB Card: Qwen3.8-Flash-Next NVFP4 on One RTX PRO 6000
It wants ~186 GB resident; the card has 96 GB. Offloading the PLE n-gram table to host RAM closes the gap: the SGLang config, the patch, and the...
-
 August 24, 2026
Streaming the Experts: Is FreeToken Better Than llama.cpp's --cpu-moe?
FreeToken streams MoE expert weights from host RAM over PCIe. Against llama.cpp --cpu-moe on an RTX 5090 with Qwen3.5-122B-A10B: 1.8x decode, 4.7x prefill.
-
 August 17, 2026
Prefill Heats the House, Decode Doesn't
Prefill pulls 570W and decode 277W on the same RTX 5090, which makes construction spec takeoff the best winter heating workload in an 85°F basement.
-
 August 15, 2026
Qwen3.8-27B on Three Boxes: 2.5× Decode, 36× Prefill
Qwen3.8-27B on the $1,000 Xeon 2x P5000, two 5070 Tis, and a 5090. Decode is 2–2.5×. Unique prefill is up to 36×, which is what TeraContext actually waits...
-
 July 31, 2026
The Junk Drawer Upgrade: What 64 GB of Forgotten DDR4 Taught Me About Quantization
Adding $50 of forgotten DDR4 to a $1,000 eBay Xeon box: four of five quant upgrades made models slower, and the only win was the one the model...
-
 July 20, 2026
The $1,000 Box, One Month On: A Model Zoo and Multi-Token Prediction
The $1,000 eBay Xeon box now serves 44 models, including four 200B-plus giants. Multi-token prediction lifted Qwen3.5-122B decode 52%, where acceptance is high.
-
 July 7, 2026
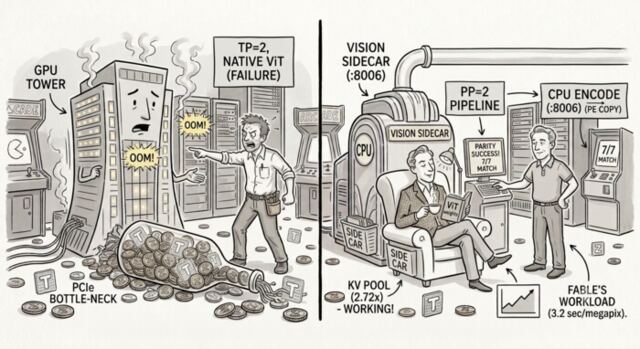
Evicting the Vision Encoder to the CPU (and Why We Shipped None of It)
How a FastAPI CPU vision sidecar freed VRAM, unlocked NVFP4 under tensor parallelism on two RTX 5070 Tis, and why the boring config still won production.
-
 July 6, 2026
The Nightly From Hell: Bisecting vLLM to Find a Working NVFP4 Build
Getting Qwen3.6-35B's native NVFP4 build running on two RTX 5070 Tis: an undocumented SM120 crash fix, and bisecting nine vLLM nightlies to find a clean pin.
-
 July 3, 2026
What AI Developers Have in Common With Three-Year-Olds on the Boardwalk
Two RTX 5070 Tis, one 35B MoE model. Why pipeline parallelism beat tensor parallelism 1.9x on prefill on consumer Blackwell cards with no GPU-to-GPU P2P link.
-
 June 21, 2026
200 Billion Parameters for $1,000: Running 4-Bit Quants on eBay Hardware
Running Qwen3.5-122B, MiniMax-M2.7, and DeepSeek-V4-Flash on a 15-32GB GPU plus cheap RAM with llama.cpp --cpu-moe, benchmarked on a $1,000 eBay Xeon.
-
 April 17, 2026
Revisiting LegalBench: New Models, A Bug I Missed, and a New Leader
Adding Qwen3.6-35B and Qwen3.5-122B to the LegalBench lineup — plus fixing an extraction bug that was quietly suppressing scores on 34 MAUD tasks.
-
 April 13, 2026
Chasing an 8% Decode Regression in vLLM Nightlies on Desktop Blackwell
How a controlled bisection traced an 8% Qwen3.5-35B decode slowdown to PR #38152 — a deliberate runtime regression accepted to fix a 4x cold-compile-time hit.
-
 April 1, 2026
Dedicated OCR Models vs Vision LLMs vs Tesseract: What Actually Works in 2026?
Benchmarking LightOnOCR, GLM-OCR, Qwen3.5, and Tesseract on 1,403 documents. Configuration matters more than model choice.
-
 March 19, 2026
David vs. Goliath: Why Bigger AI Isn't Always Better at Law when David is 6 months younger than Goliath
A 27B quantized model outperforms a 120B heavyweight across 161 legal reasoning tasks. LegalBench results from local inference on consumer GPUs.
-
 March 17, 2026
Migrating a Fully Customized OpenClaw Deployment into NVIDIA NemoClaw
A practical account of migrating an always-on AI assistant with 20 skills, local inference, and LAN integrations into NVIDIA's NemoClaw sandbox runtime.
-
 March 16, 2026
Perishable Inventory: What GPUs and Apartments Have in Common
Both industries sell time-bound capacity. Both are converging on the same playbook.
- February 28, 2026 Running MiniMax-M2.5 on a Single RTX 6000 Blackwell: 68 Tokens/s with 64K Context How to run the 139B parameter MiniMax-M2.5 model on a single NVIDIA RTX PRO 6000 Blackwell GPU using SGLang, achieving 68 tokens/s with 64K context.
- February 26, 2026 Running Qwen3.5-35B on an RTX 5090 with vLLM: A Practical Guide How to solve the Triton autotuner OOM crash when running Qwen3.5-35B-A3B on an RTX 5090 with vLLM, using cross-GPU cache warmup for reliable inference.
-
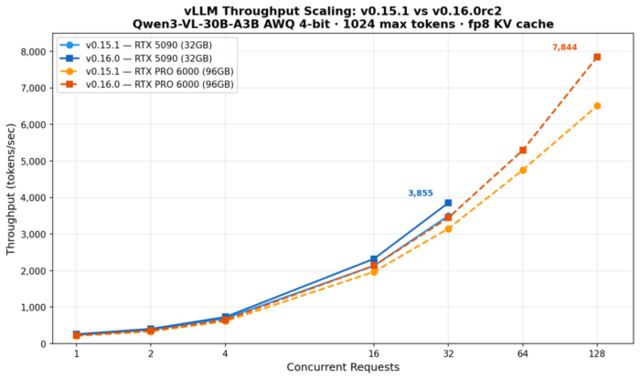 February 25, 2026
vLLM v0.16.0 Delivers Up to 20% Higher Throughput on Blackwell GPUs
vLLM v0.16.0rc2 vs v0.15.1 on RTX 5090 and RTX PRO 6000 with Qwen3-VL-30B-A3B: 8-10% faster at moderate load, 20% at 128 requests (7,844 tok/s).
-
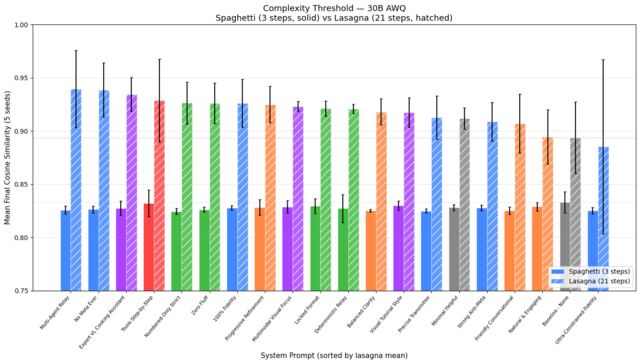 February 22, 2026
System Prompts and Semantic Drift: 500 Paraphrase Chains Reveal What Works, What Backfires, and Why Model Size Changes Everything
20 system prompts, two Qwen3 models, 500 telephone-game runs: rankings didn't carry across models (rho = 0.15), and prompts mattered only on complex tasks.
-
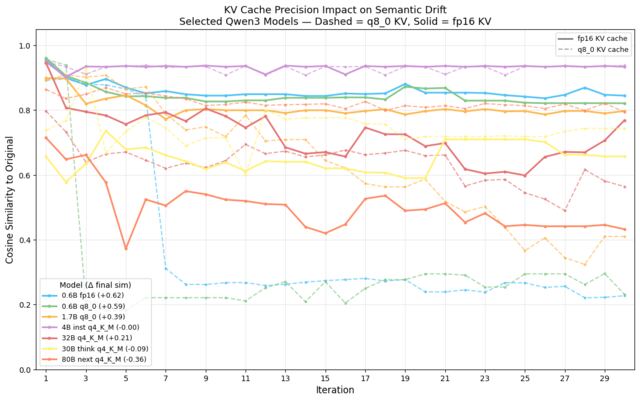 February 21, 2026
One Config Change, 22 Models, Wildly Different Results: How KV Cache Precision Reshapes Semantic Drift in Qwen3
22 Qwen3 models, two KV cache precisions, 30-iteration paraphrase chains. fp16 KV rescued the smallest model (+0.62) and collapsed the largest (-0.36).
-
 February 20, 2026
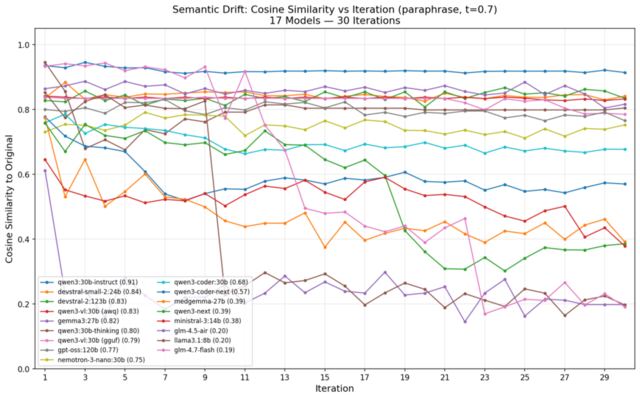
The Telephone Game for Local LLMs: Quantifying Semantic Drift Across 17 Open-Weight Models in 30-Iteration Paraphrase Chains
30-iteration paraphrase chains on 17 local LLMs: Qwen3-instruct held 0.91 similarity, Llama 3.1:8b collapsed to 0.20, and AWQ beat GGUF in long chains.
-
 February 15, 2026
Do LLM Inference Engines Actually Get Faster With Updates?
Re-running our vLLM, SGLang, and Ollama benchmarks a month later: vLLM NVFP4 hit 8,430 TPS (+4.9%), and fixing Ollama's config beat any version bump.
-
 January 31, 2026
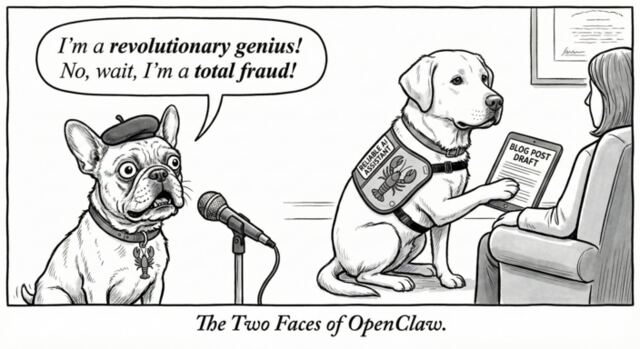
OpenClaw: The Overhyped French Bulldog of AI Agents or a Dependable Labrador?
Is OpenClaw a neurotic French Bulldog—trendy but plagued by issues—or a steadfast Labrador service dog, reliable and ready to serve?
-
 January 24, 2026
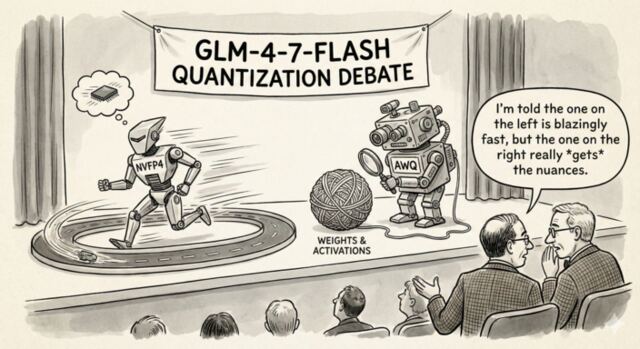
This Week's Hottest Model: GLM-4.7-Flash Quantization Showdown
Comprehensive benchmarks comparing FP4 and AWQ-4bit quantizations of GLM-4.7-Flash on accuracy (MMLU, GSM8K) and throughput scaling.
- January 23, 2026 The Decision Chart: Which Model Should You Actually Use? (Part 5) After 200+ GPU-hours and 300,000+ inference calls, here's what to actually deploy based on your VRAM, task type, and latency requirements.
-
 January 22, 2026
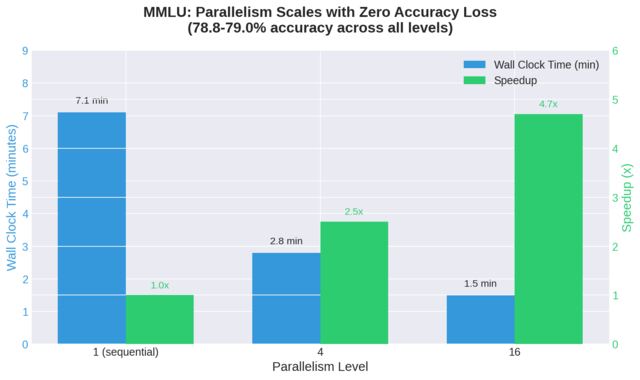
Scaling vLLM: How Parallel Queries Change Everything (Part 4)
Testing vLLM with 1, 4, and 16 concurrent queries revealed near-linear scaling with zero accuracy loss. GSM8K scaled 9.2x faster at parallel=16.
- January 22, 2026 GLM-4.7-Flash: 128k Context on a Single Consumer GPU How to run ZAI's powerful 30B MoE model with 128k context on an RTX 5090 using vLLM and MLA optimization.
- January 21, 2026 Own It or Rent It? The Real AI Decision for Small Business When should your business run AI locally versus using cloud services? We break down the real trade-offs with help from our AI debate platform.
-
 January 21, 2026
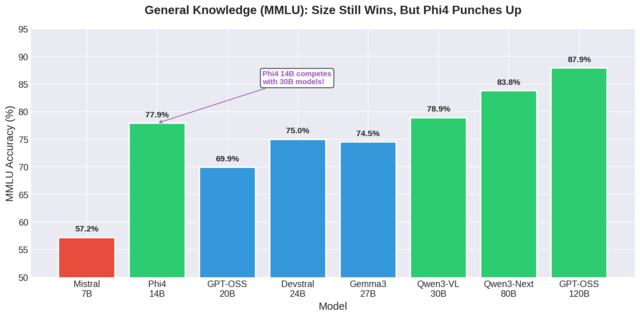
The Model Shootout: Architecture Trumps Scale (Part 3)
Phi4 at 14B achieves 95.1% on GSM8K math, matching 80B models. Mistral-7B collapses to 53.1%. Model size alone doesn't predict capability.
-
 January 20, 2026
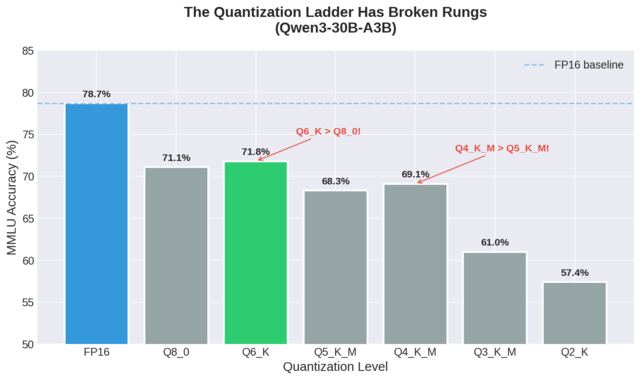
The Quantization Ladder Has Broken Rungs (Part 2)
Q6_K outperforms Q8_0 on accuracy. Q4_K_M beats Q5_K_M. The smooth quantization curve is a myth—K-quant schemes break the rules.
-
 January 19, 2026
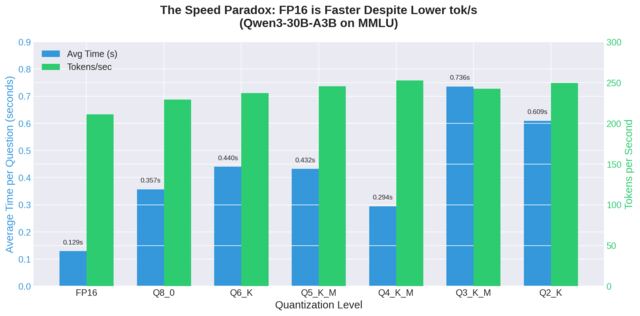
600,000 Questions Later: When Your GPU Doubles as Home Heating (Part 1)
FP16 models are often faster than quantized versions despite being larger. The tok/s vs time-to-answer paradox changes how we should evaluate LLM speed.
- January 16, 2026 Friday Morning Space Heaters: The Real Cost of Quantization Benchmarking Qwen3 models at 4-bit vs 8-bit while warming the house during a cold snap
-
 January 10, 2026
Benchmarking LLM Inference: vLLM vs SGLang vs Ollama on NVIDIA Blackwell
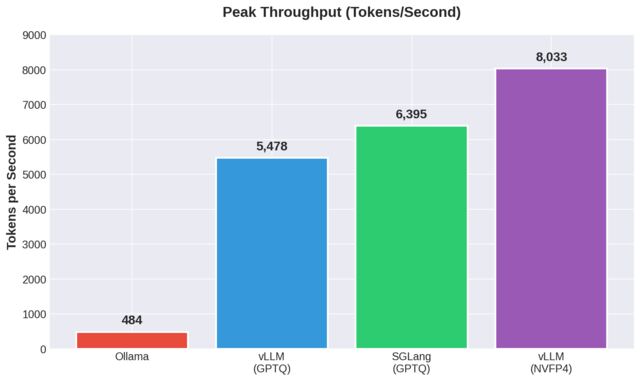
We benchmarked vLLM, SGLang, and Ollama running Llama 3.1 8B on an RTX PRO 6000 Blackwell. vLLM with NVFP4 hit 8,033 TPS; SGLang beat vLLM by 17% on...
- January 9, 2026 1,200 Tokens Per Second for Under $500 Four Blackwell GPUs on Llama 3.1 8B: the $450 RTX 5060 Ti hits 1,259 TPS, and the $8,500 workstation card is only 5x faster. Memory bandwidth beats price....
- January 5, 2026 1,000x Cheaper: Why Local RAG Changes Everything vLLM embeddings hit 8,091 chunks/sec—385x faster than cloud. A $1,000 RTX 5070 Ti reranks 329 docs/sec. RAG changes everything.
- January 5, 2026 The Math Says Cloud Wins. The Math is Wrong. RTX 6000 Blackwell Pro Q-Max vs OpenRouter: at 8 hours/day of batched inference, the GPU pays off in 5 years. Latency and privacy may be worth the premium....
- January 5, 2026 I Spent $8,500 on a GPU to Beat Cloud AI. Here's What Happened. I benchmarked GPT-OSS 120B, Gemma 3 27B, and Qwen 3 VL 30B locally vs OpenRouter. The results surprised me—cloud is often cheaper, but throughput changes everything.
- January 1, 2026 Top 7 AI Privacy Risks Virginia Businesses Can't Ignore in 2026 A practical guide to AI privacy risks for Virginia businesses, including VCDPA compliance, data protection, and actionable steps to protect your company.
- December 30, 2025 Does AI Agree With Itself? A Self-Consistency Experiment I asked an AI to classify 1,400 specs it created. It agreed with itself 99.86% of the time. Here's why that matters for your business.
- December 28, 2025 Which Qwen Should You Use? A Practical Benchmark for SMBs I tested 9 LLM models on 5 practical SMB tasks. GGUF beat AWQ by 13%. Dense models won at math. Here's what actually matters for your business.
- December 27, 2025 The Copilot Audit: A Thought Experiment for SMBs A thought experiment on Microsoft 365 Copilot ROI: audit your licenses today and you'd likely find 45% usage and $27K a year in right-sizing savings.
- December 23, 2025 Can AI Sound Like Someone? Part 2: The Results 10 AI models, 12 personalities, 1,440 responses. The slowest model crushed the fastest, a 14B tied one 10x its size, and reasoning models were unusable.
- December 22, 2025 AI Without the BS: A Small Business Leader's Survival Guide A practical guide for small business leaders navigating AI implementation. Skip the hype, avoid the pitfalls, and build AI that actually works for your team.
- December 22, 2025 Can AI Learn to Sound Like Someone? Can an AI trained on theology imitate a famous theologian better than a general-purpose AI? The specialist knew the facts. The generalist captured the voice.
- December 17, 2025 What Building a Minesweeper AI Taught Us About LLM Limitations A prompt engineering journey that reveals the uncomfortable gap between AI capabilities and expectations—and why that matters for your business.
- December 16, 2025 AI Loses at Playing Battleship but Wins at Coding It After beating frontier LLMs at Battleship 5-0, the real story: Claude one-shotted the entire game app. What agentic coding means for small business.
- December 15, 2025 The Hall of Mirrors: Benchmarking Grokipedia vs Wikipedia for RAG Pipelines A benchmark comparing Grokipedia and Wikipedia for RAG pipelines reveals both sources have subtle biases—and using them together may be the smartest strategy.
- December 15, 2025 Grok Comments on the Joshua8.AI Grokipedia Benchmark We asked Grok to respond to our benchmark comparing Grokipedia vs Wikipedia for RAG pipelines. Here's what the AI behind Grokipedia had to say.
- December 12, 2025 This Week's Friday Night Experiment: Why Speculative Decoding Didn't Speed Up My 120B Model (And Why That's Actually Fine) Testing Eagle3 speculative decoding on GPT-OSS-120B with one RTX PRO 6000 Blackwell GPU. The baseline won, but the journey taught me more than the result.
- December 5, 2025 Sudoku Night: 79 Models, One Puzzle, and My Wife 79 LLMs take on the NYT's easy Sudoku and get humbled by a human who finished in 59 seconds while using less power than a light bulb.
- December 1, 2025 A More Detailed Look at 'Even a Screw Works as a Nail If You Hit It with a Big Enough Hammer' 620+ runs across 73 local models and 10 frontier APIs reveal the brutal truth: pure LLM reasoning fails where 31ms of Python succeeds with mathematical certainty.
- November 26, 2025 Even a Screw Works as a Nail If You Hit It with a Big Enough Hammer 35+ LLM models vs one Python script: a Friday-night experiment proves tool usage beats pure reasoning by six orders of magnitude on the classic Mastermind puzzle.
- November 4, 2025 The Vibe Coding Trap: Don't Trade Old Tech Debt for New AI Slop in 2025 AI coding agents promise to fix technical debt fast, but vibe coding often creates new AI-generated 'slop.' Learn to use AI wisely without trading old debt for new....
- October 17, 2025 Prompt Engineering vs. Context Engineering: Lessons from the Game of Clue in 2025 The difference between prompt engineering and context engineering for AI systems, and when to use each, explained through the classic board game Clue.
- July 26, 2025 You Are Bad at AI Because You Suck at Golf: Precision, Patience & Strategy Discover the surprising parallels between golf and AI development. Learn why precision, patience, and strategic thinking are essential for success in both domains.
- July 21, 2025 Mastering LLM Limitations: Context Windows, Inference Engines & RAG Optimization Deep dive into LLM context window limits, inference engine constraints, RAG strategies, and optimization techniques for processing large documents effectively.
- July 14, 2025 Navigating Privacy in AI Chatbots: Policies, Practices & Secure Alternatives Complete guide to AI chatbot privacy policies, data handling practices, SnitchBench results, and secure alternatives like local LLMs for businesses.
- April 27, 2025 Navigating LLM Inference Models: Llama, Gemma, Phi, Mistral & DeepSeek Compared Comprehensive comparison of popular LLM inference models including Llama, Gemma, Phi, Mistral, and DeepSeek - features, performance, and selection guide.
Interesting Industry Reads
Curated external resources and research papers on AI trends and business applications.
State of AI in Business 2025 Report
MIT Technology Review & MLQ.AI
This report reveals a stark "GenAI Divide" in enterprise AI: despite $30-40 billion in investment, 95% of organizations see zero ROI from GenAI initiatives. While tools like ChatGPT boost individual productivity, enterprise-grade systems struggle with adoption—only 5% reach production due to brittle workflows and lack of contextual learning. The key finding: success isn't determined by model quality or regulation, but by implementation approach. Organizations that prioritize process-specific customization, demand systems that learn and adapt over time, and partner externally achieve twice the success rate. The highest performers report measurable value through reduced BPO costs, improved customer retention, and selective workforce optimization in support and engineering roles.
Prompt Politeness Research: Two Contrasting Perspectives
"Should We Respect LLMs? A Cross-Lingual Study on the Influence of Prompt Politeness on LLM Performance" (Yin et al., 2024)
"Mind Your Tone: Investigating How Prompt Politeness Affects LLM Accuracy" (Dobariya & Kumar, 2024)
Two recent studies examine how prompt politeness affects LLM performance, arriving at nuanced but seemingly divergent conclusions. Yin et al.'s cross-lingual study across English, Chinese, and Japanese reveals that impolite prompts often degrade performance, while overly polite language provides no guarantees—politeness effectiveness varies significantly by cultural and linguistic context. Their research emphasizes that LLMs mirror human communication traits, suggesting culturally-aware prompting strategies matter. Conversely, Dobariya and Kumar's controlled experiment using 250 prompts across mathematics, science, and history found that impolite prompts (84.8% accuracy) consistently outperformed polite ones (80.8% accuracy) in ChatGPT 4o. This counterintuitive result challenges conventional assumptions about human-AI interaction. The apparent contradiction highlights critical implementation factors: newer model architectures may process tone differently than legacy systems, task domain influences politeness sensitivity (creative vs. analytical), and cultural context remains paramount in multilingual deployments. For practitioners, these findings suggest that prompt engineering should prioritize clarity and directness over social politeness conventions, while remaining cognizant of cultural variables in global applications. The research underscores that effective AI interaction requires moving beyond anthropomorphic assumptions—what works in human communication may not optimize machine performance. Both studies agree on one principle: blindly applying human social norms to LLM interactions can undermine accuracy and effectiveness.